[C109] TwinQuant: Decoding-Aware Dual-Centred Quantization for Diffusion Language Models
Abstract
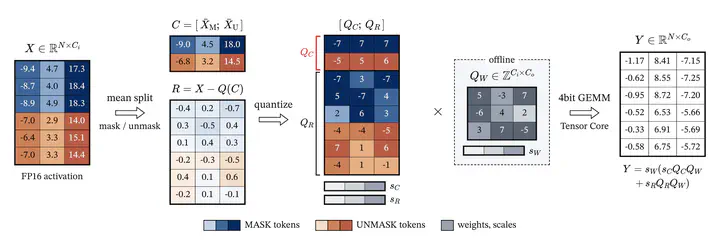
Block-diffusion language models repeatedly process a partially masked block as decoding progresses. At each step, masked and revealed tokens coexist but have different activation centers, while teacher forcing omits intermediate inference states. The result is wasted activation range and weight calibration against the wrong distribution. TwinQuant aligns quantization with the decoding process. TwinZero centers the two token states separately using online statistics, while TwinCal calibrates weights on centred activations collected along the model’s own denoising trajectory. Together, they place activation quantization and weight reconstruction in the same state-conditioned coordinate system, reducing W4A4 degradation across both evaluated model families without changing the decoding trajectory. On Nemotron-Labs-Diffusion-8B, TwinQuant achieves up to 2.3× prefill and 2.8× decoding speedups without quality degradation.

Seokho Han (한석호)
Integrated BS-MS student

Chaehyeon Min (민채현)
Integrated BS-MS student

Junwon Lee (이준원)
MS student
