[C110] SPIRA: Sparse Pre-RoPE Informed Routing Attention for Diffusion Language Models
Abstract
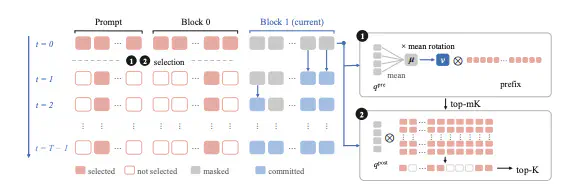
Block diffusion language models generate a block of tokens at a time, denoising the block’s masked positions in parallel. Each denoising step attends from the remaining masked positions to the whole prefix, so the block opens with a full-prefix selection made for every masked position in it. Sparse attention makes this practical, and prior block-diffusion methods reuse selection or attention information across denoising steps. We identify a redundancy that this reuse does not remove. At the block’s initial denoising step, the masked queries are strongly aligned before RoPE. Their alignment is higher than after RoPE and than that of preceding decoded queries across all three models. Their full-prefix searches are therefore near-duplicates. SPIRA uses one shared routing query to search the prefix once, followed by an exact rescoring of the candidates it returns, both once per block. It reduces how many queries perform the full-prefix search, so it is orthogonal to selectors that narrow the key side. On LongBench, SPIRA matches dense attention on SDAR-4B at the largest budget we evaluate, outperforms Quest at every matched budget across three diffusion LMs by up to 13.4 points in macro average, and cuts the cost of the block attention stage by up to 11.0× at a 131k prefix with batch size 1.

Chaehyeon Min (민채현)
Integrated BS-MS student

Seokho Han (한석호)
Integrated BS-MS student

Junwon Lee (이준원)
MS student
