[C112] Quantization-Aware Test-Time Training for Feed-Forward 3D Gaussian Splatting Codecs
Abstract
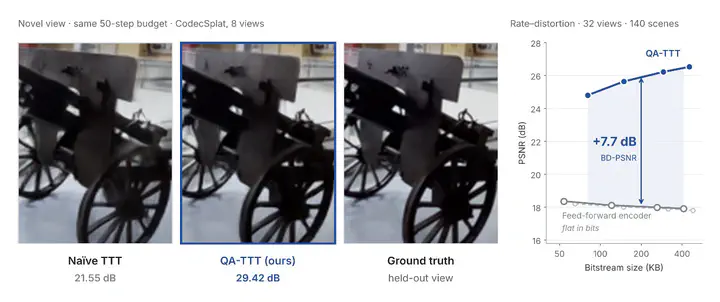
Feed-forward (FF) 3D Gaussian splatting (3DGS) codecs map posed images to an entropy-coded scene in a single forward pass. The latent transmitted by their amortized encoder, however, is not the one that minimizes distortion for the given scene at the given bit cost. We quantify this amortization gap with quantization-aware test-time training (QA-TTT), in which the encoder refines the latent of each scene by rendering the decoded scene into the context views only, with the quantizer inside the optimization loop. On two codecs with opposite latent designs, a pixel-aligned latent (CodecSplat) and global tokens (a codec built on TokenGS), evaluated on 140 DL3DV-10K scenes at four rate points each, QA-TTT improves BD-PSNR by 1.8–7.7 dB, an order of magnitude more than encoder-side optimization achieves in 2D learned image compression. For the pixel-aligned latent the gain grows with the number of input views, from 1.8 dB at 8 views to 7.7 dB at 32, where the FF encoder collapses to 18 dB regardless of the bit budget; for global tokens the gain is 3.0 dB at every view count. Optimizing the continuous latent and quantizing afterwards is 0.7–2.4 dB worse at matched rate and, for the pixel-aligned codec, falls below the FF encoder itself. With QA-TTT, a 3DGS codec outperforms both 2D image transmission with receiver-side reconstruction and, at high rate, the uncompressed FF backbone.

Chanung Park (박찬웅)
Combined MS-PhD student
