[C115] Reducing Iterative Runtime Overheads in Block-Diffusion LLM Inference on an Edge Device
Abstract
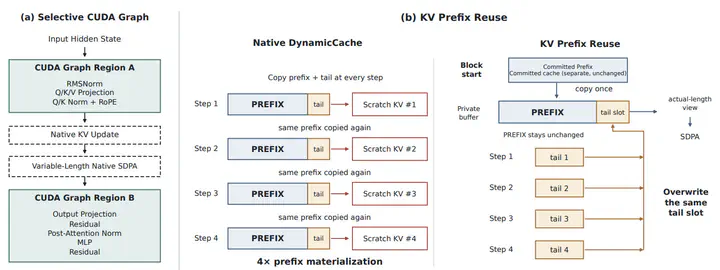
Block-diffusion language models enable parallel token refinement but introduce repeated runtime overhead during iterative denoising, potentially limiting their efficiency on resource-constrained edge devices. This work characterizes OPDLM inference on an NVIDIA Jetson Xavier NX and identifies repeated host-side kernel submissions and redundant KV-prefix materialization as key sources of runtime overhead. Based on these observations, we apply selective CUDA Graph replay to fixed-shape Transformer operations and reuse the invariant KV prefix across denoising steps while preserving the original decoding behavior. Experimental results show that selective CUDA Graph replay reduces generation latency by 23.83%, with KV prefix reuse providing an additional 3.55% reduction. We further observe that the relative benefits of these optimizations vary with sequence length, revealing distinct scaling characteristics of runtime overhead in block-diffusion inference. These results demonstrate that reducing iterative runtime overhead improves inference efficiency on a resource-constrained edge GPU.

Woosung Chung (정우성)
Combined MS-PhD student
