[C116] Truncation-Aware Multi-Bit Training for Low-Bit ANN-to-SNN Conversion
Abstract
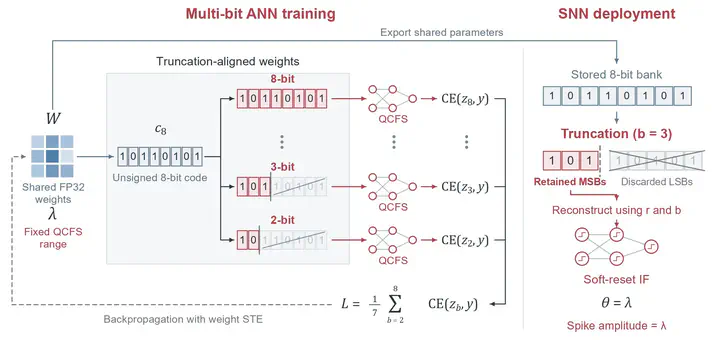
Multi-bit quantization allows artificial neural networks (ANNs) to share weights across several precisions. For variable-precision layers, truncating a single stored 8-bit bank supports these precisions without separate weight banks or requantization from floating-point weights. However, low-bit weights produced by rounding during training can differ from those reconstructed by truncation. In converted spiking neural networks (SNNs), this mismatch can alter weighted spike inputs and firing under fixed conversion parameters. We present multi-bit quantization-aware training (QAT) to recover low-bit SNN accuracy by aligning ANN training weights with deployment truncation. The method jointly trains batch-normalization-folded weights across 2–8 bits using shared channel ranges. Quantization clip-floor-shift (QCFS) activation ranges and folded biases remain fixed, allowing all precisions to share neuron parameters without bit-specific corrections. Under equal training budgets, identical conversion settings, and the same deployment truncation, the method improves converted-SNN accuracy over rounding-based QAT by 25.59-46.46 pp at 2 bits and 5.81-19.69 pp at 3 bits across VGG-16 and ResNet-18 on CIFAR-10/100.
Chanwook Hwang (황찬욱)
Combined MS-PhD student
